
Manual data collection or blocked sources slowing the team down?
Send the source. We’ll review the cleanest extraction path.
Web Scraping & Data Extraction
Stop losing hours to manual data collection
Your competitors already have automated feeds. You are still copy-pasting. We turn messy web sources into clean datasets, so your team can move faster.
What usually breaks first
Most teams lose 10+ hours every week to manual data collection; copy-pasting from websites, chasing outdated spreadsheets, and paying premium prices for data subscriptions that never quite fit. When the source changes, the process breaks.
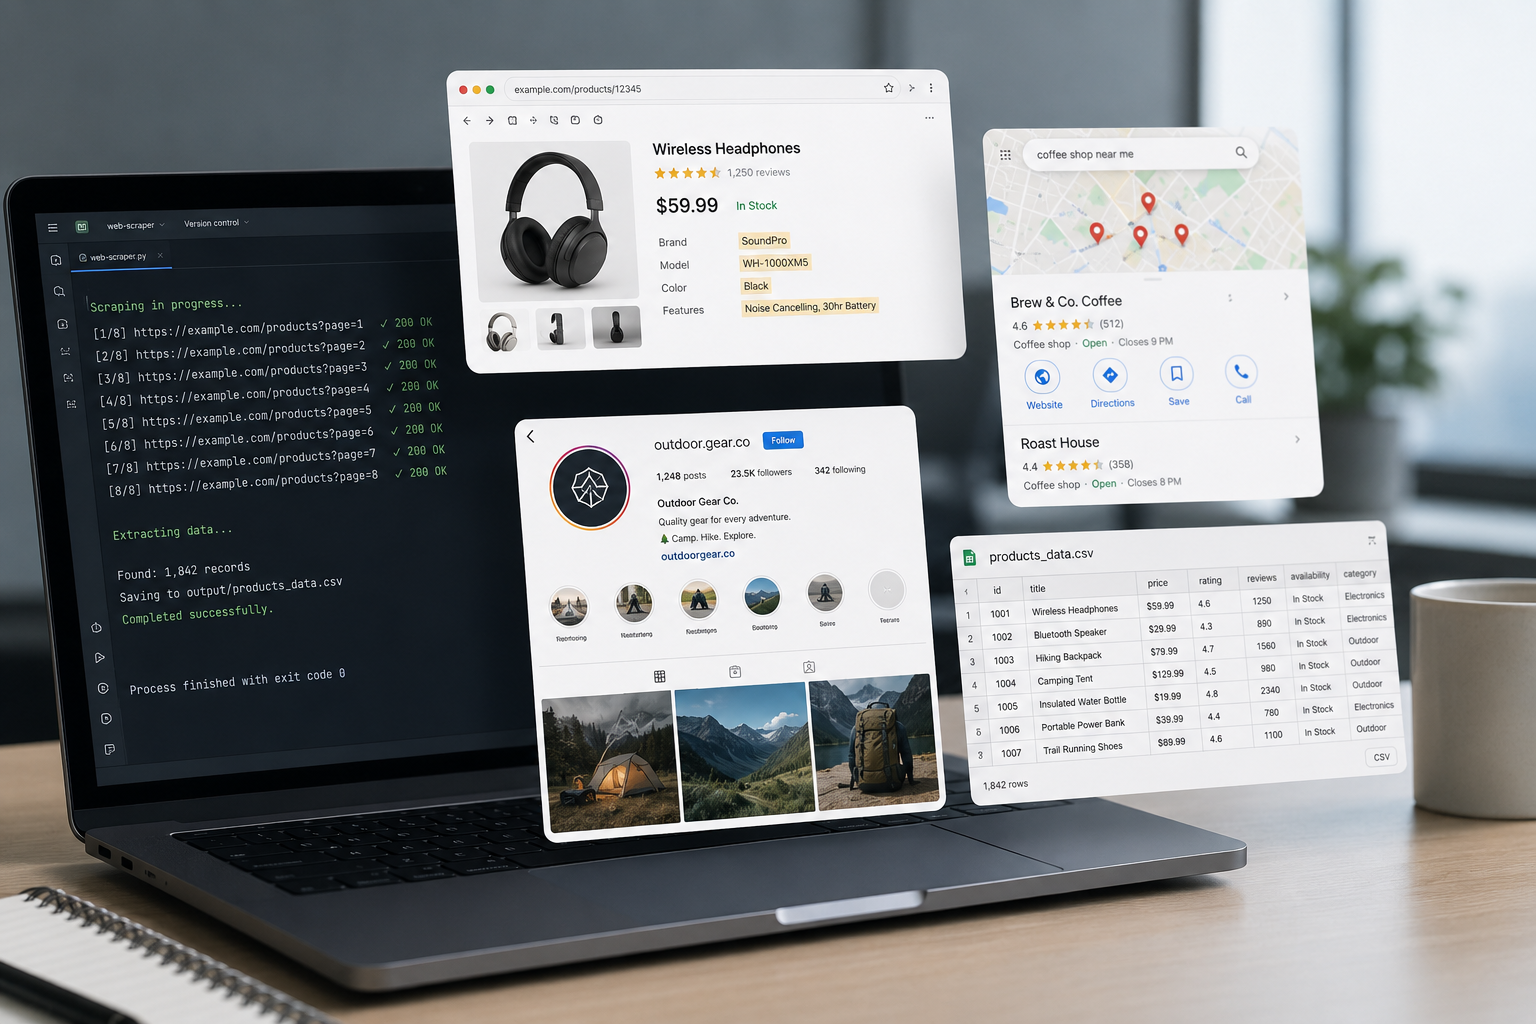
Reliable web data pipelines for teams tired of manual collection
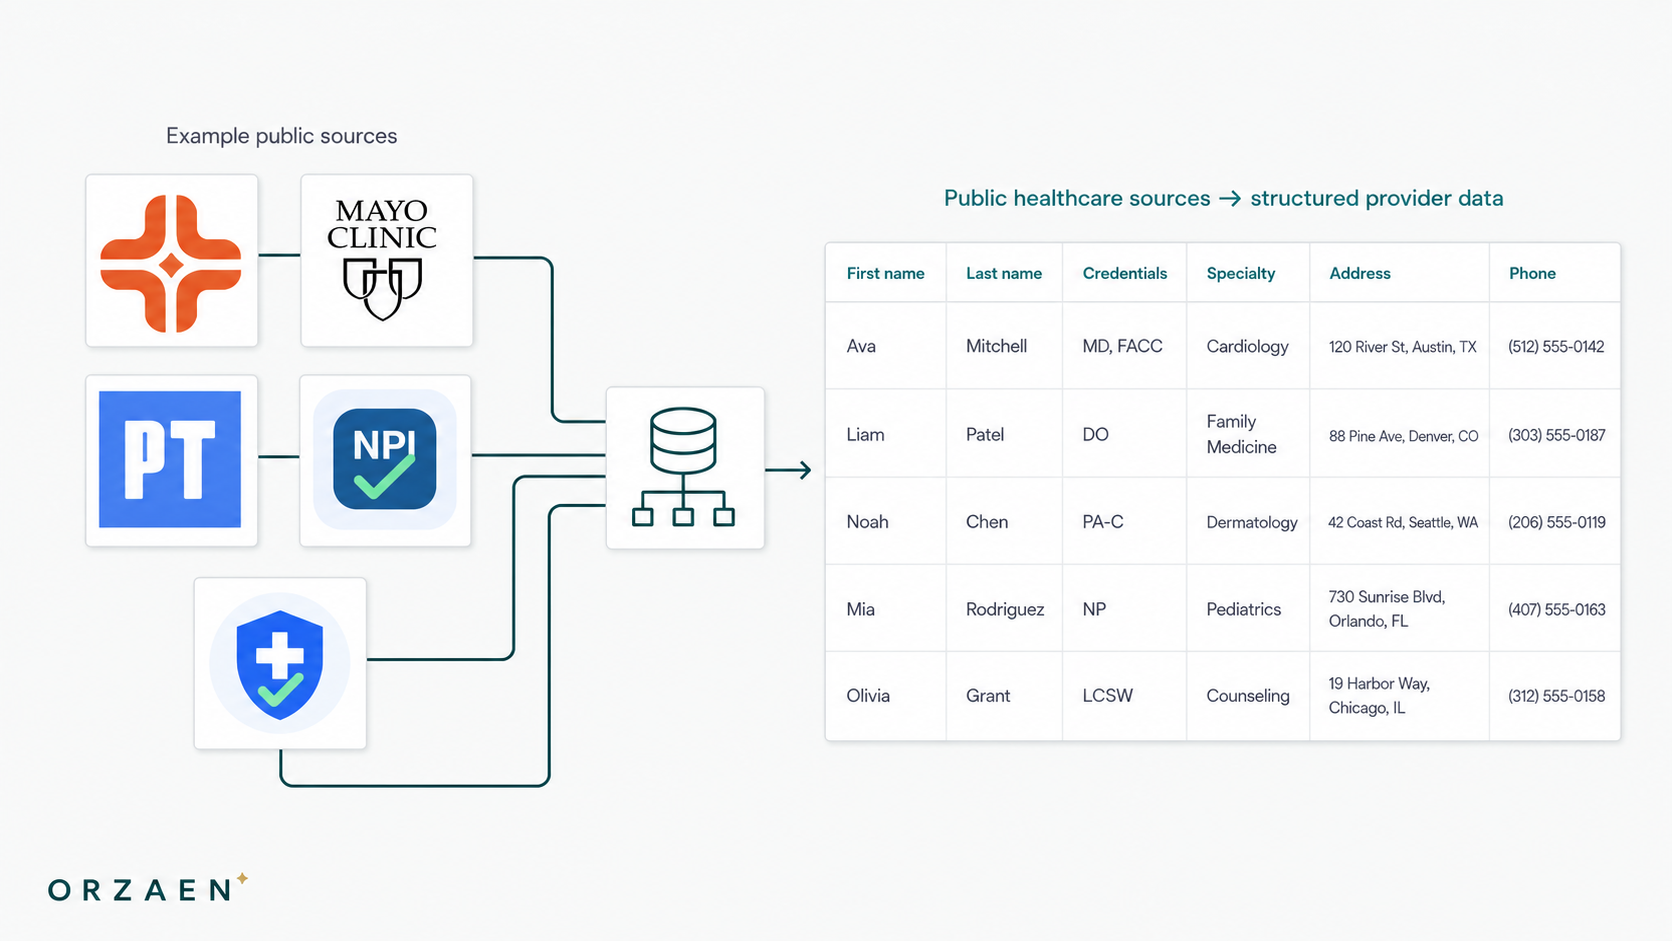
At Orzaen, we build custom extraction workflows for websites, directories, e-commerce platforms, PDFs, login portals, hidden APIs, mobile app endpoints, and protected sources where access is permitted.
We inspect the source first, then choose the cleanest stable path: static crawling, browser automation, hidden APIs, OCR, AI cleanup, session handling, proxy rotation, or scheduled data pipelines. The result is clean structured data delivered in the format your workflow needs.
Client Feedback
“Wonderful to work with, knowledgable and kind! Great work!”
Karah S. / CRM Operations Manager, MarketSurge User
Barriers We Remove
The parts that usually break first
We turn fragile sources into stable extraction workflows your team can rely on.
Market Intelligence
Competitors already track pricing and listings
Our Solution
Automated feeds keep teams informed
Revenue Operations
Lead lists decay before outreach begins
Our Solution
Fresh data improves campaign timing
Compliance
Manual checks miss source changes
Our Solution
Monitoring flags changes before risk
Operations
Teams waste hours collecting records
Our Solution
Scheduled extraction removes repeat work
Finance
Messy documents delay reporting workflows
Our Solution
OCR converts files into records
Data Quality
Duplicate records break downstream systems
Our Solution
Validation keeps datasets usable
Services
Extraction systems built around your actual data source
Web, Directory & API Extraction
Extract structured data from websites, directories, search portals, login flows, JavaScript-rendered pages, hidden APIs, GraphQL endpoints, and backend network calls.
Bot-Protection & Access Resilience
Handle rate limits, blocked requests, session expiry, rotating IPs, browser fingerprints, CAPTCHA workflows, Cloudflare challenge pages, retries, and source changes with responsible extraction controls.
E-commerce & Price Monitoring
Collect product catalogs, SKUs, prices, inventory, variants, images, supplier data, marketplace listings, and competitor price changes through scheduled tracking systems.
Lead, Social & Market Intelligence
Build datasets from company directories, professional profiles, social platforms, YouTube, forums, comments, job boards, real estate sources, and market research platforms.
OCR, PDF & Public Records Extraction
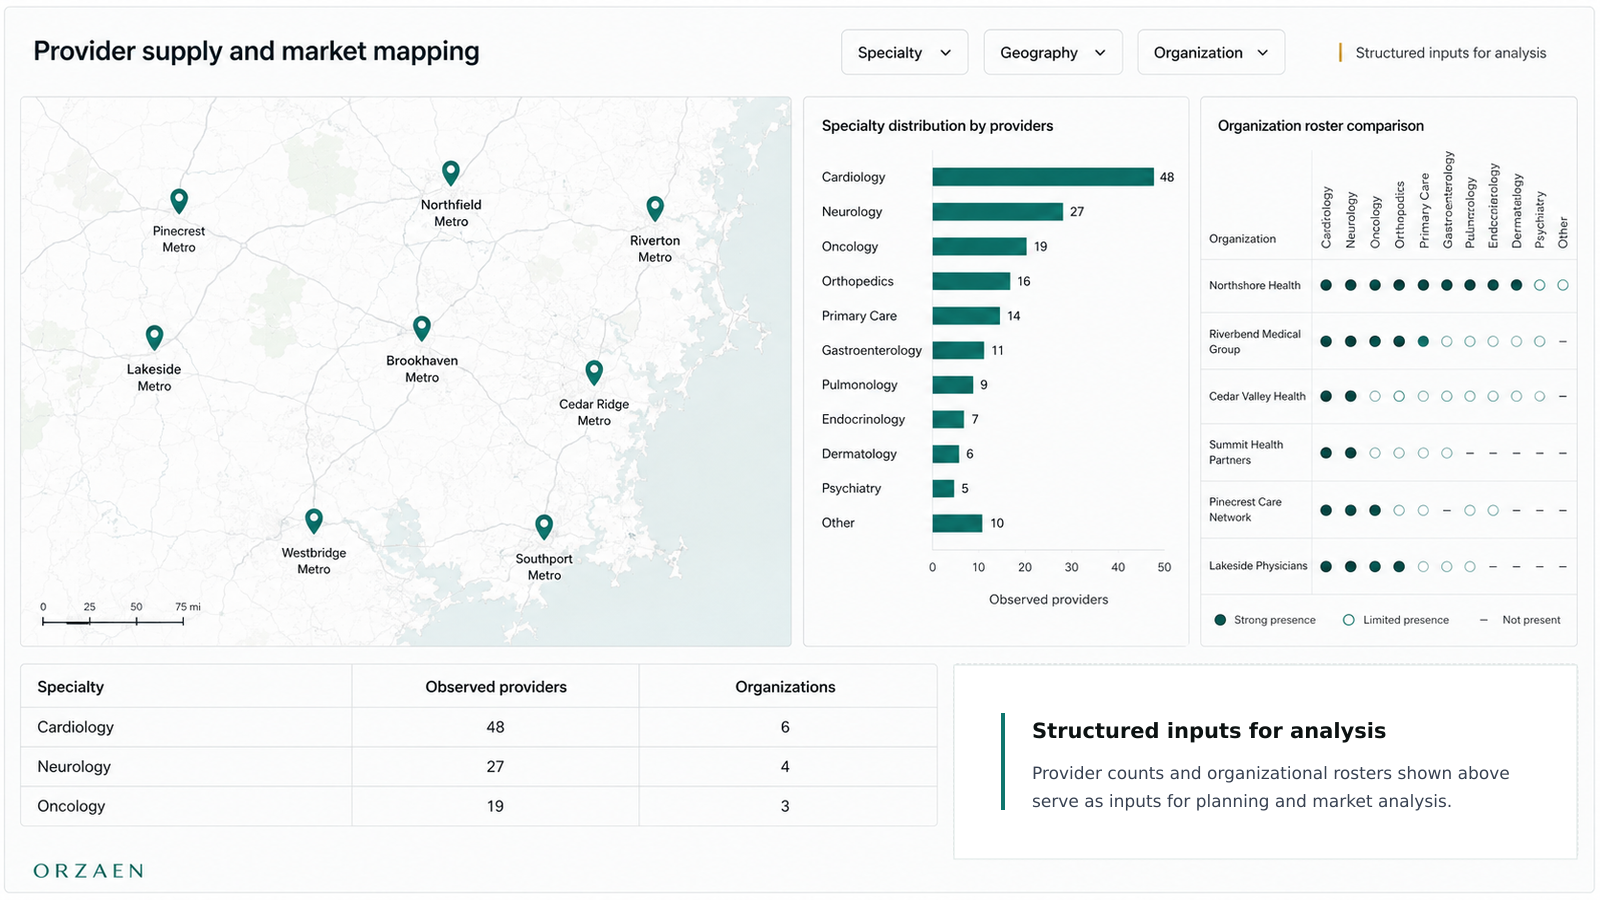
Process scanned PDFs, image-based files, invoices, reports, government portals, licenses, patents, healthcare records, and other public or regulated data sources.
Scheduled Data Pipelines & Delivery
Build recurring extraction systems with cleaning, deduplication, validation, databases, Google Sheets or Airtable sync, API delivery, dashboards, webhooks, alerts, and handover documentation.
Use Cases
What teams automate with extracted data
Case Studies
Proof from real client work

Data Sources
Sources we can turn into usable data
Source Registry
Websites
Approach
Static HTML parsing for simple pages. JavaScript rendering via Playwright/Selenium for dynamic SPAs. Rate limiting, retry logic, and proxy rotation for resilience.
Output
Structured JSON, CSV, or database records with normalized fields and deduplicated entries.
Examples
Directories, listings, news sites, blogs, documentation portals, job boards, review aggregators.
Data Types
Data organized for decisions, reporting, and operations
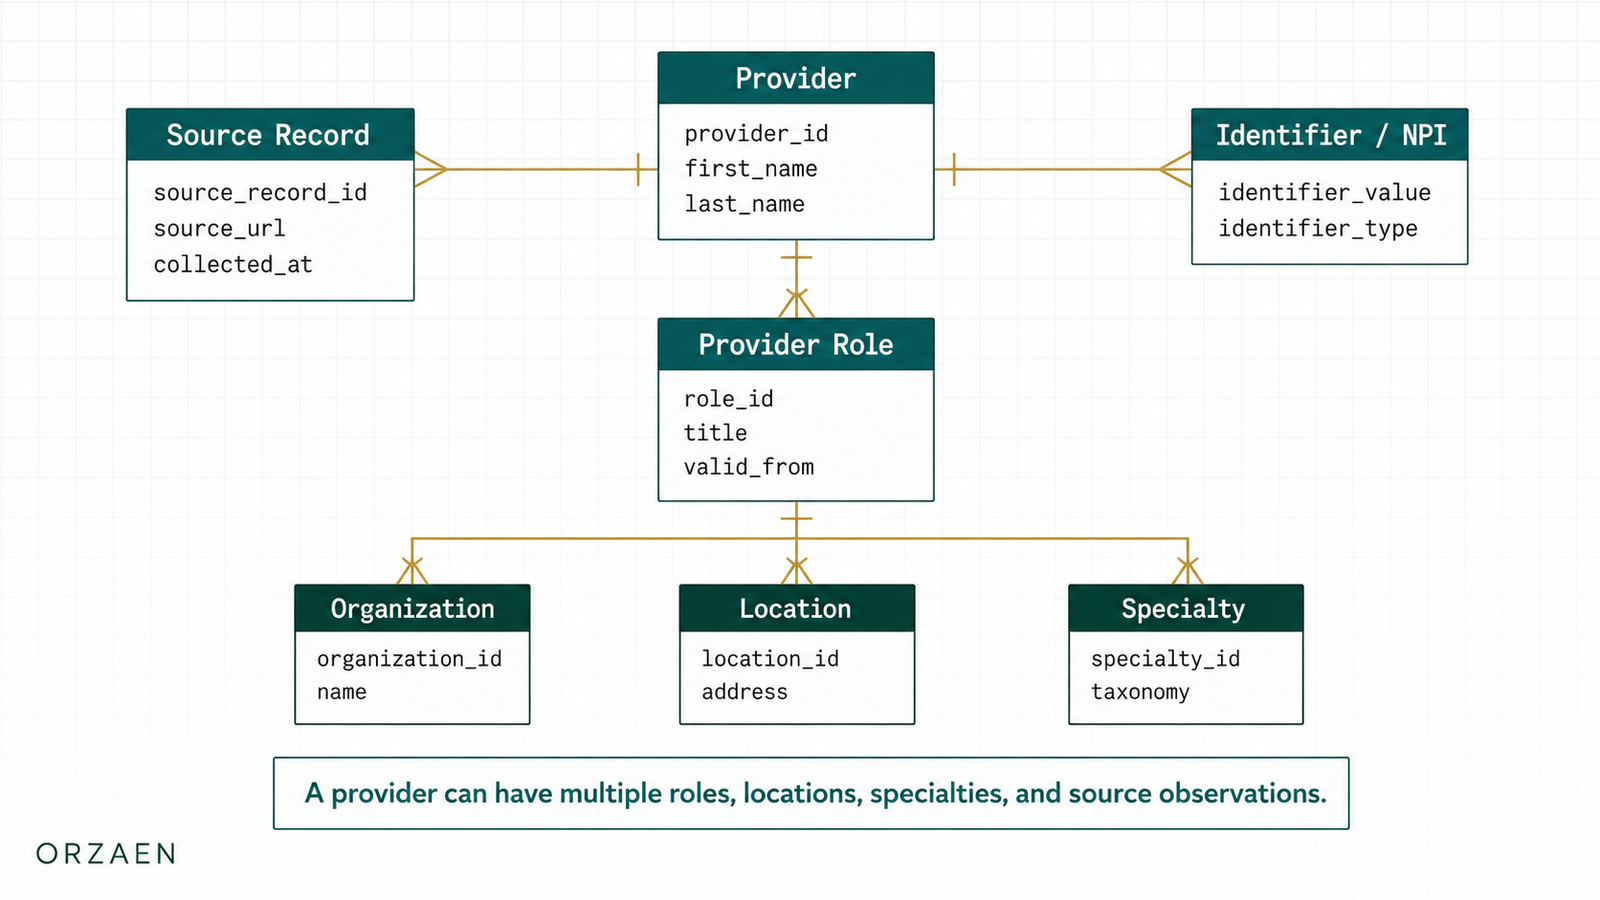
We do not just collect raw rows. We structure the output around how your team will search, compare, verify, and use the data.
Commerce & Product Intelligence
Product catalogs, prices, inventory, reviews, restaurants, vehicles, and marketplace listings.
Products · Reviews · Prices · Inventory · Restaurants · Vehicles
Lead & Organization Data
Company profiles, directories, contacts, jobs, professional profiles, and business metadata.
Companies · Contacts · Jobs · Profiles · Directories
Social & Community Signals
Social posts, comments, forums, hashtags, engagement, creator data, and audience activity.
Posts · Comments · Forums · Hashtags · Engagement
Market & Search Intelligence
Search results, keyword trends, news, articles, rankings, SERP data, and market visibility signals.
Search Results · Keywords · News · Articles · Rankings
Public & Regulated Records
Government portals, licenses, patents, healthcare listings, public datasets, and official records.
Licenses · Patents · Healthcare · Public Records · Government Data
AI & Analytical Datasets
Clean structured datasets prepared for AI systems, analytics, enrichment, and internal workflows.
AI Data · Training Data · Analytics · Enrichment · Internal Data
Production Stack
Built with tools that support reliable extraction at scale
We use proven automation, parsing, validation, storage, and delivery tools depending on the source complexity and business workflow.
01
Acquisition
Tools for stable collection from public sites, portals, dynamic pages, and source-specific workflows.
 Python
 Playwright
 Selenium
 Browser Bots
 Automation Scripts
02
Access Stability
Controls for sources with sessions, rate limits, changing access behavior, or blocking patterns.
03
Processing
Cleanup, normalization, enrichment, and document extraction workflows.
 Pandas
 DuckDB
 OCR
04
Scale & Scheduling
Systems for recurring jobs, large volumes, queues, and controlled execution.
 Apache Spark
 Apache Kafka
 Apache Airflow
 Cron Jobs
05
Storage & APIs
Structured storage and backend layers for searchable, reusable datasets.
 PostgreSQL
 MongoDB
 Redis
 FastAPI
 Docker
06
Delivery
Exports and handoff formats your team can actually work with.
 Google Sheets
 Airtable
 Looker Studio
 Webhooks
07
Alerts
Notifications when extraction jobs complete, fail, get blocked, or detect changes.
 Gmail
 Slack
Data Pipeline
Our implementation blueprint
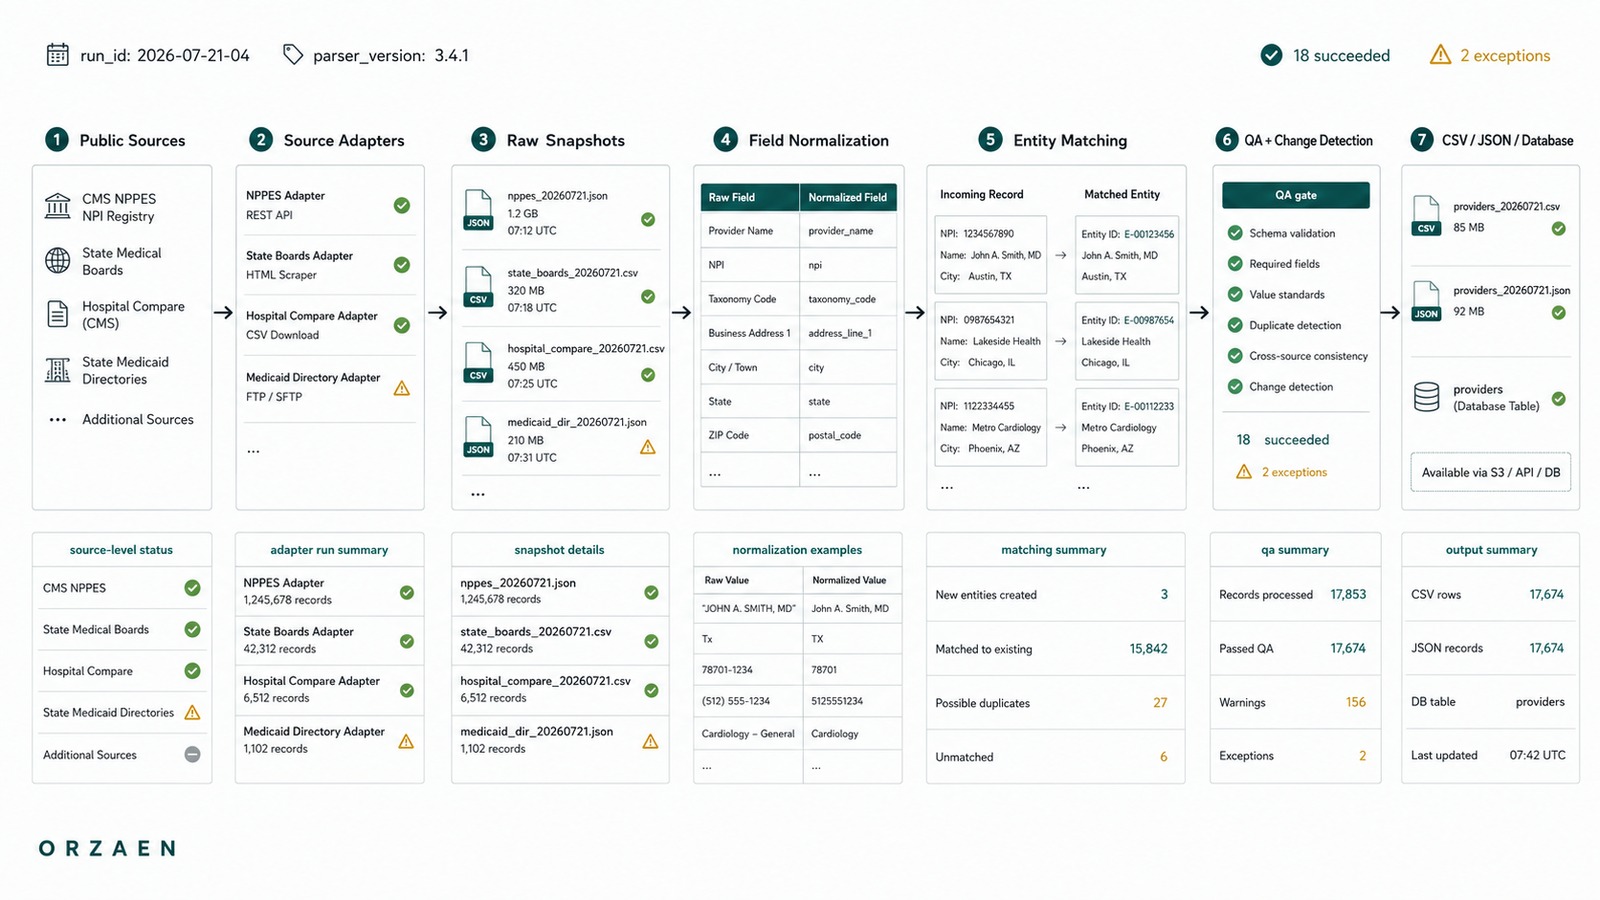
We follow a controlled extraction methodology so your data workflow is stable, repeatable, and ready for real business use.
Review the sources
We inspect the websites, pages, logins, pagination, hidden APIs, and available fields before building.
Set up extraction
We choose the right method: crawler, browser automation, API extraction, or scheduled scraping.
Clean the data
We remove duplicates, fix formats, normalize fields, and turn raw scraped records into usable data.
Add quality checks
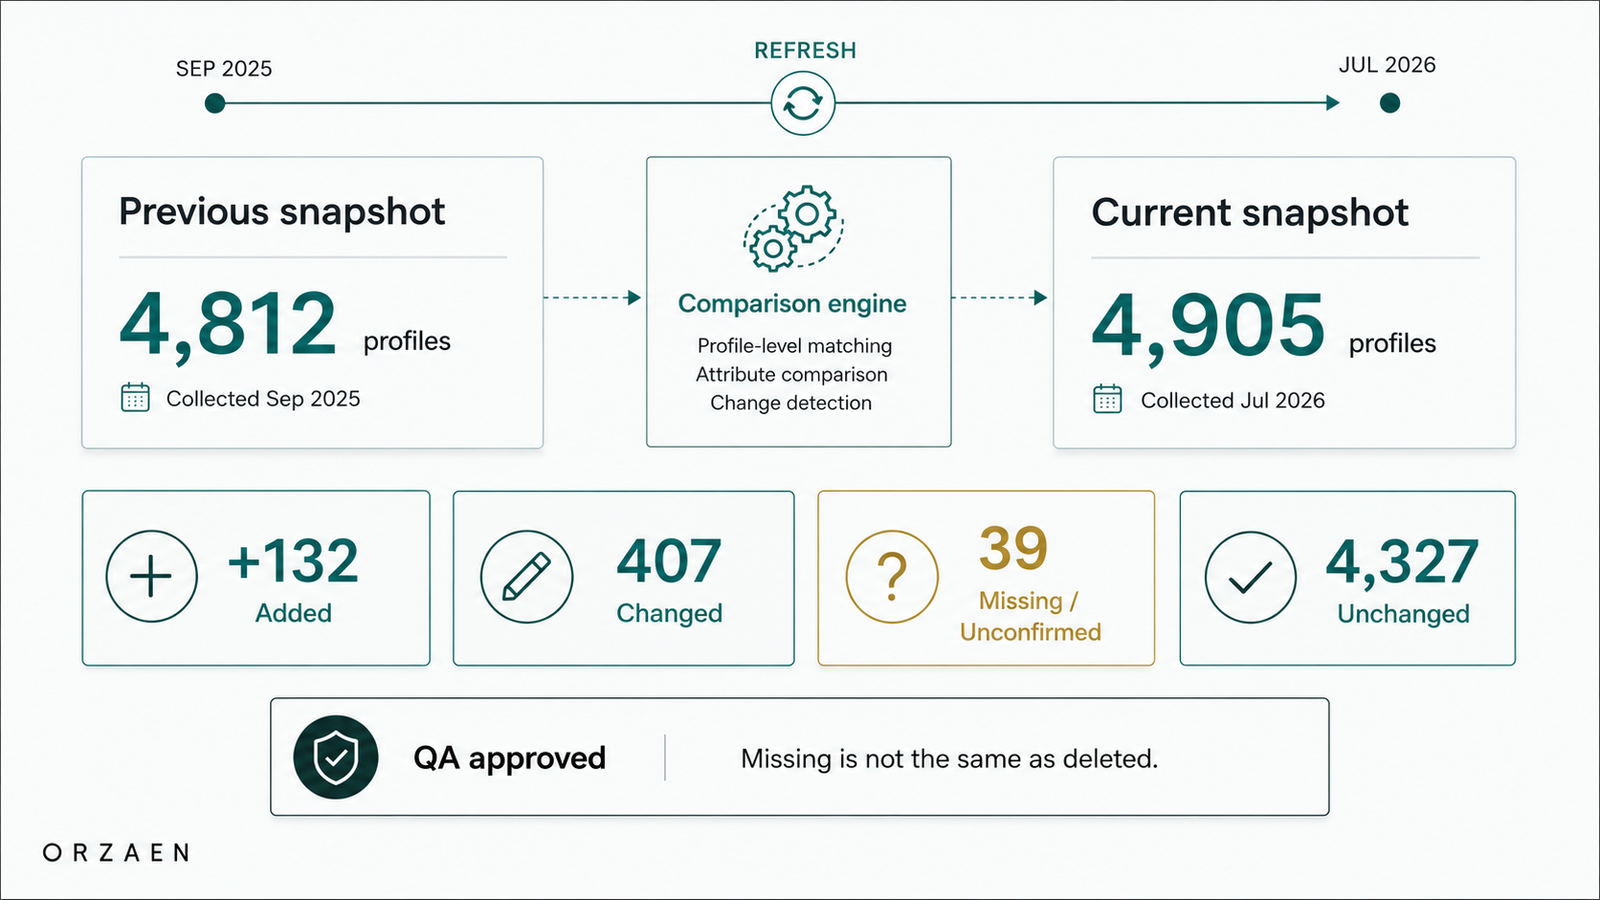
We check missing fields, failed requests, changed layouts, duplicate rows, and incomplete runs.
Deliver usable output
You receive clean CSV, Excel, Sheets, JSON, database records, dashboards, or scheduled exports.
Controlled Workflow
Every layer connects source access, extraction method, cleanup, validation, and delivery into one production workflow.
FAQ
Questions clients ask before starting extraction
Still have questions? We typically respond within 2 hours.
Automation Field Notes
Lessons from building automation that runs in production
Request a Quote
Turn messy web sources into usable data
Manual collection, broken sources, messy exports — send the source, and we’ll map the cleanest extraction path.
No perfect brief needed.
Project Brief