
Messy data slowing decisions?
Send the source file, export, or database problem. We’ll map a cleanup and enrichment plan.
Data Processing & Enrichment
Stop making business decisions with dirty data
We clean messy CSVs, CRM exports, scraped datasets, spreadsheets, product catalogs, and reporting files. We remove duplicates, fix broken fields, enrich missing data, validate records, and deliver clean output ready for dashboards, AI tools, databases, and business workflows.
Where dirty data starts costing money
Most teams already have the data they need, but it is scattered, duplicated, incomplete, inconsistent, or trapped in messy exports. Dirty data breaks reports, weakens AI tools, creates CRM confusion, and forces teams to manually fix files before they can use them.
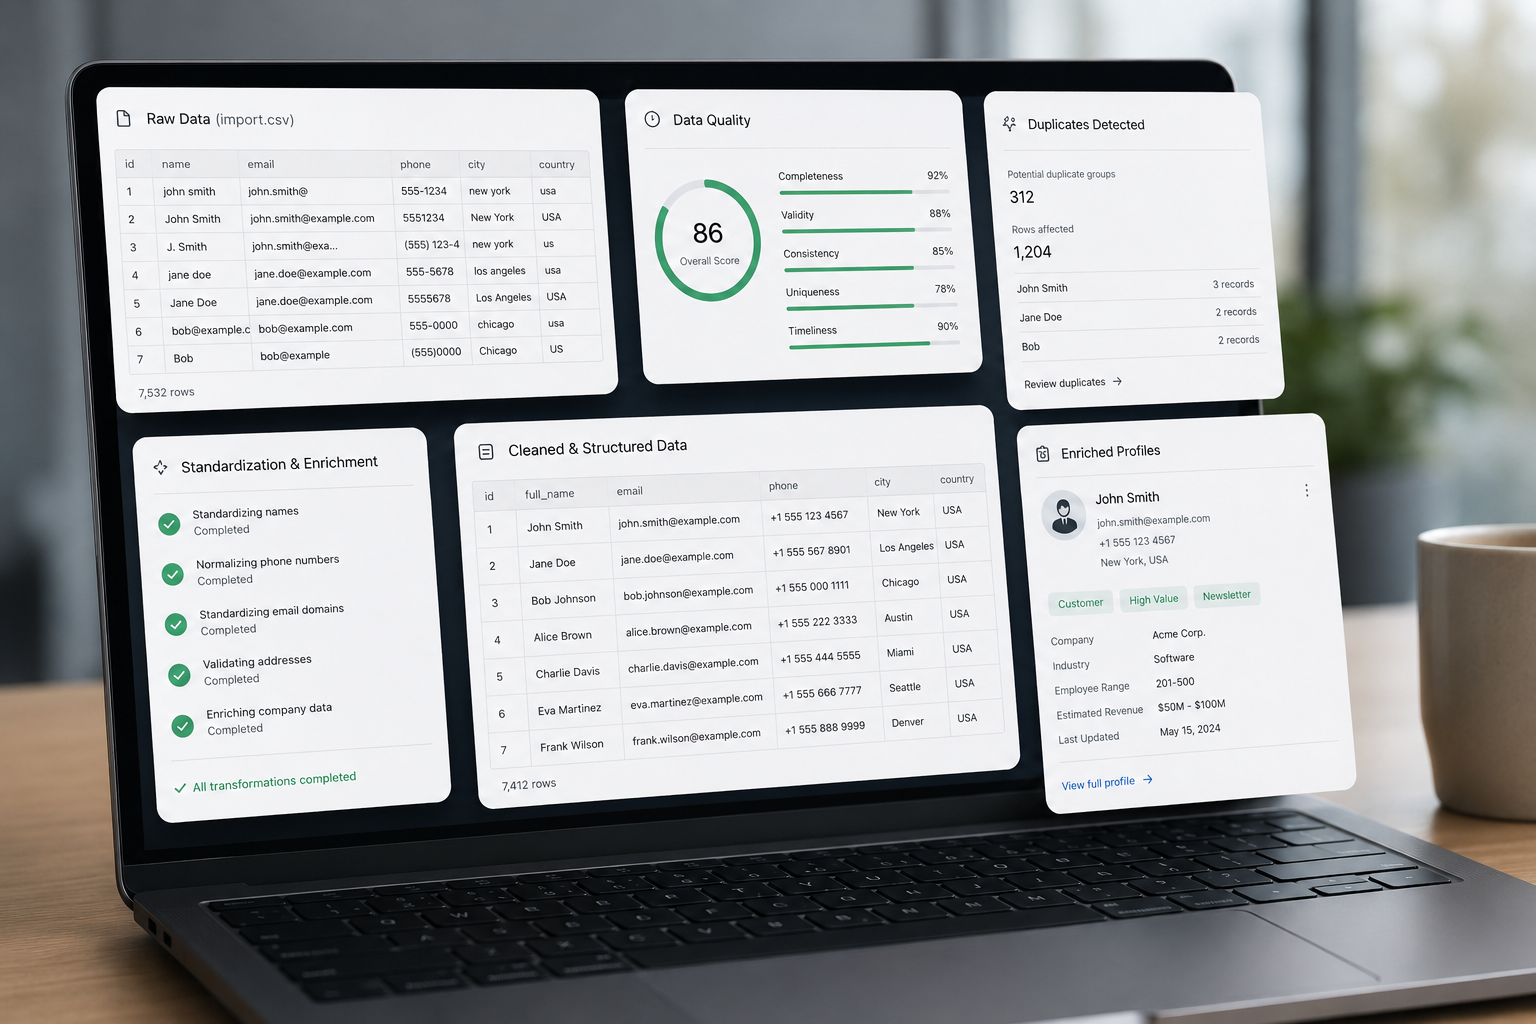
Clean, validated, enriched data your team can actually use
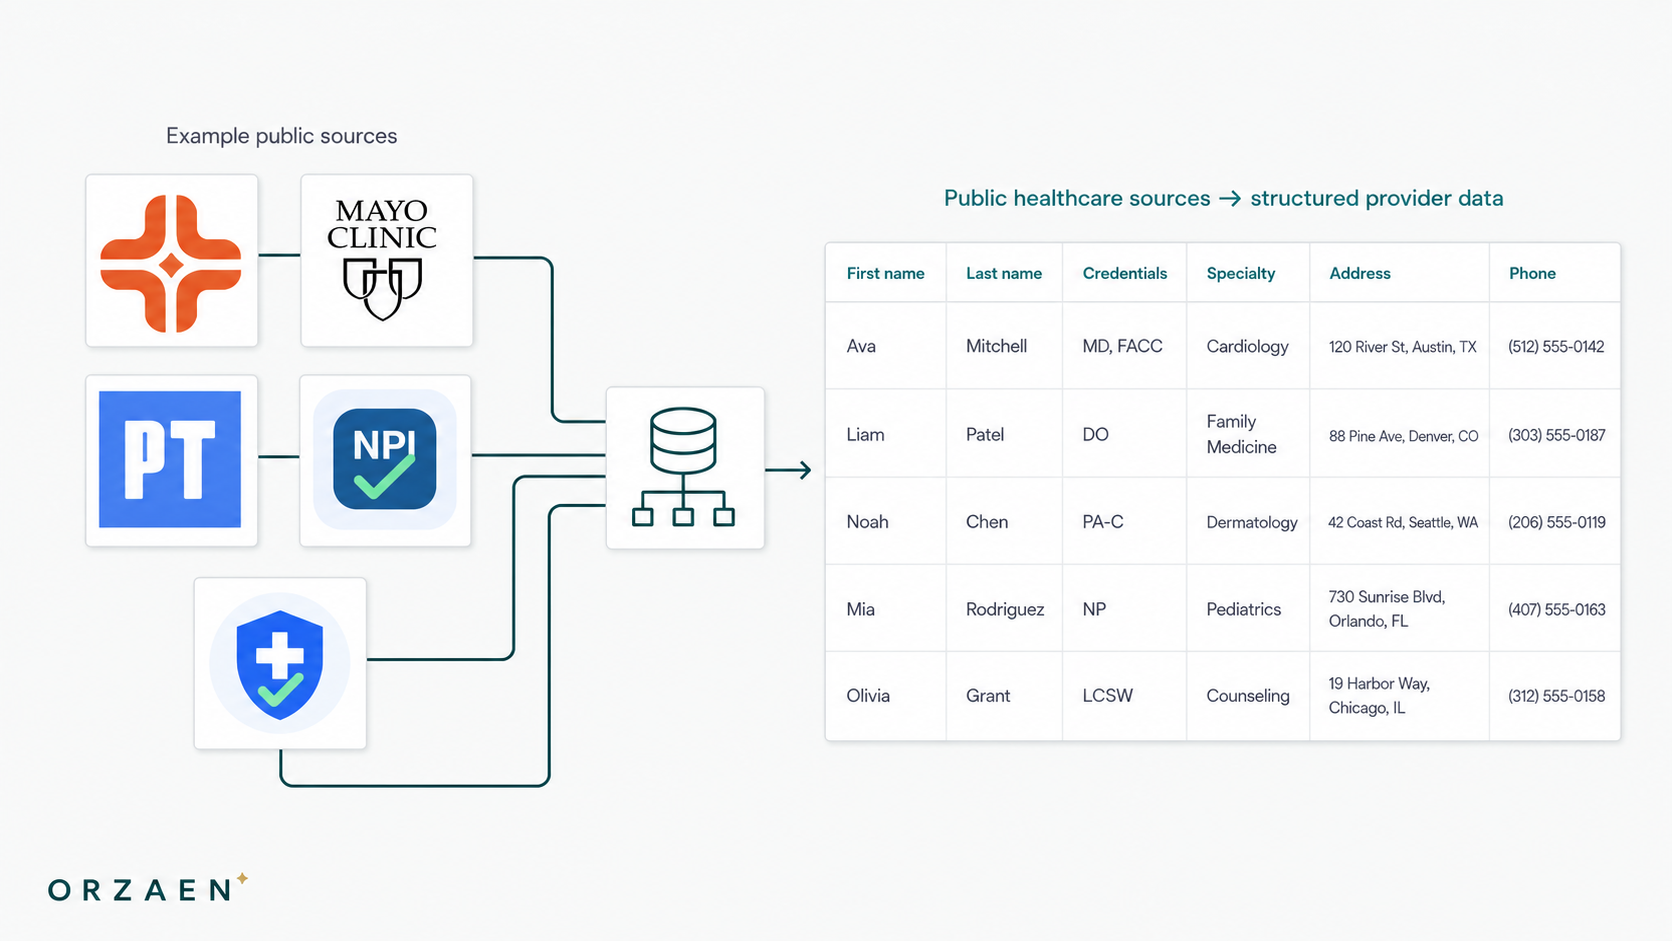
Orzaen cleans, validates, deduplicates, enriches, and structures messy business data from CSV files, Excel sheets, CRM exports, scraped datasets, product catalogs, JSON/XML files, and database exports.
We combine rule-based processing, fuzzy matching, validation checks, enrichment APIs, and AI-assisted structuring to turn raw data into clean output your team can use for dashboards, imports, outreach, reporting, AI tools, and business workflows.
Client Feedback
“Wonderful to work with, knowledgable and kind! Great work!”
Karah S. / CRM Operations Manager, MarketSurge User
Data Quality Snapshot
What improves after cleanup
A quick audit view of completeness, duplicates, validity, enrichment, and delivery readiness before and after processing.
Completeness
Missing fields resolved
Duplicate Rate
Duplicate groups reduced
Valid Fields
Emails, phones, URLs checked
Enrichment
Missing business fields added
Data Quality Barriers We Remove
The data problems that quietly break decisions
We turn messy, incomplete, duplicated, and inconsistent records into clean datasets your team can trust for reports, dashboards, AI tools, imports, and workflows.
Duplicate Records
The same customer appears 3 different ways
Our Solution
Deduplication and fuzzy matching merge records safely
Broken Contact Data
Emails bounce because formats are broken
Our Solution
Validation checks fix formats and flag bad records
Reporting Gaps
Reports do not match between systems
Our Solution
Normalization aligns fields, dates, IDs, and categories
CRM Quality
Your CRM has missing companies, phones, or industries
Our Solution
Enrichment adds missing company, contact, and lead fields
AI Readiness
Your AI, search, or dashboard gives bad answers
Our Solution
Clean schemas and quality scoring improve downstream output
Manual Cleanup
Your team manually fixes CSV files every week
Our Solution
Repeatable processing pipelines clean files automatically
Data Merging
Multiple sources use different names, formats, and structures
Our Solution
Entity resolution and reference mapping connect related records
Quality Control
Bad rows reach reports, imports, dashboards, and workflows
Our Solution
Validation rules catch errors before delivery
Services
Data processing workflows we build around messy inputs
Data Cleaning & Standardization
We fix messy columns, inconsistent formats, broken dates, casing issues, phone formats, categories, labels, missing values, and repeated manual cleanup problems.
Deduplication & Entity Matching
We identify duplicate customers, companies, vendors, products, SKUs, and leads using exact matching, fuzzy matching, and review-safe merge logic.
Data Enrichment & Field Completion
We enrich missing company, contact, location, industry, category, phone, email, and firmographic fields using APIs, lookup rules, and controlled validation.
Scraped Data Cleanup
We clean raw scraped data from websites, marketplaces, directories, portals, and public records by removing noise, fixing fields, standardizing text, and structuring output.
AI-Assisted Structuring
We use AI where rule-based cleanup is not enough: messy text extraction, category mapping, label normalization, record classification, summaries, and field completion.
Validation Reports & Delivery Files
We deliver clean files with validation notes, rejected rows, duplicate groups, confidence checks, enrichment columns, and import-ready output formats.
Use Cases
Messy data we turn into analysis-ready output
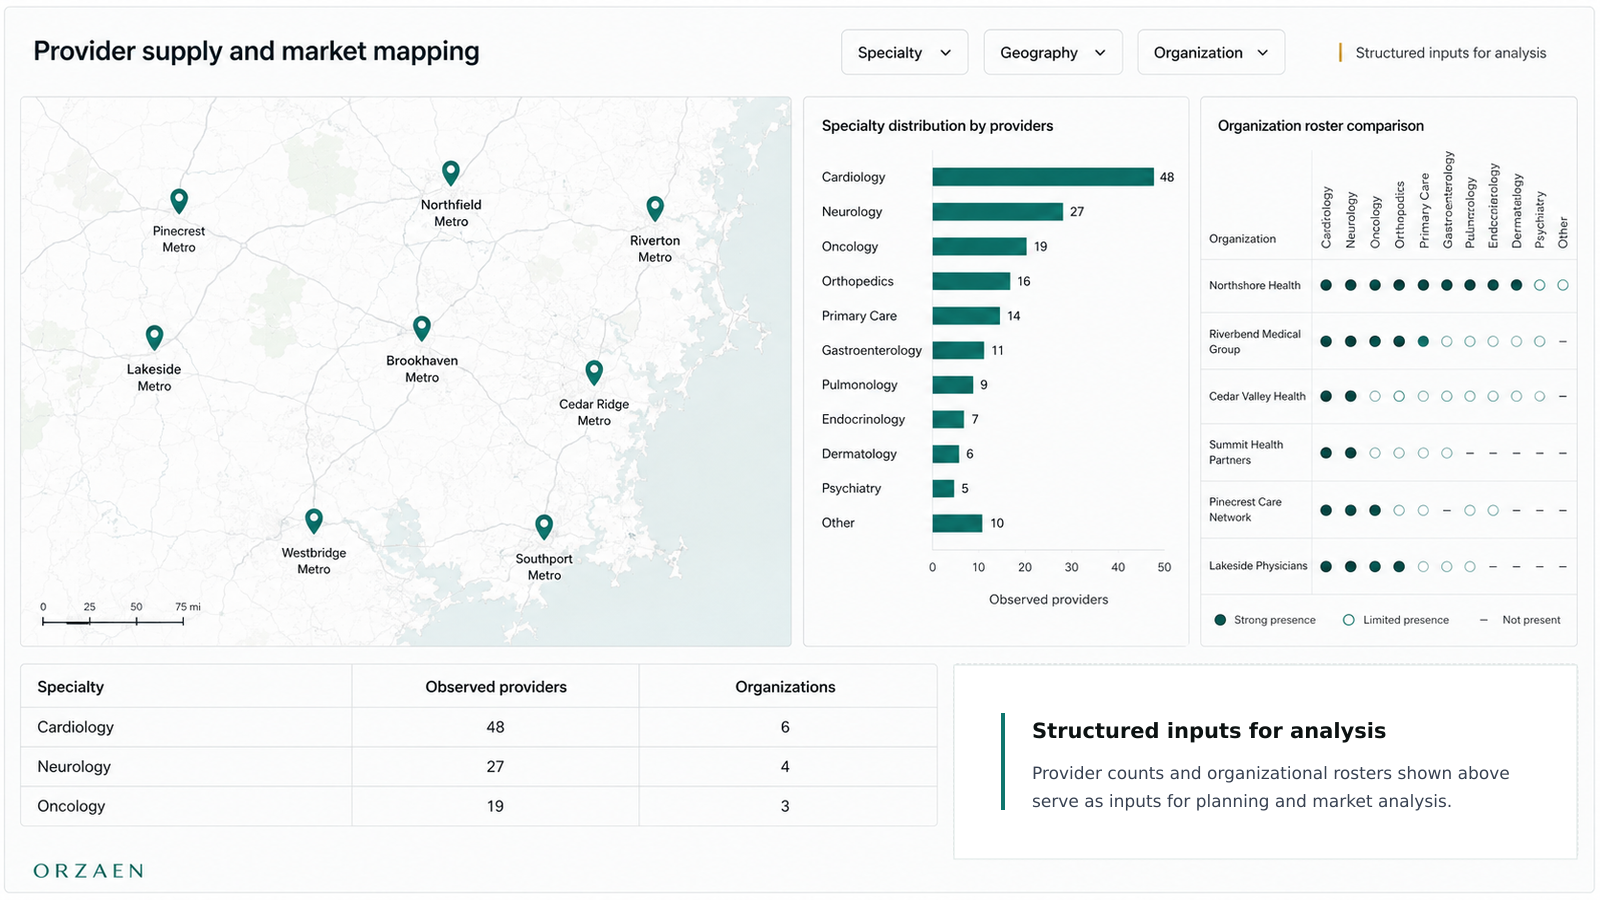
Data Processing Results
Proof from real cleanup and enrichment work

Where Data Problems Start
CRMs, spreadsheets, scraped datasets, catalogs, reports, APIs, and AI-ready text
Source Registry
CRM & Lead Exports
Approach
We clean, deduplicate, validate, enrich, normalize, and structure CRM exports so sales, marketing, and operations teams can trust the records again.
Output
Clean contact/company files, duplicate groups, invalid-field reports, enriched columns, CRM-ready import sheets, and lead-quality scoring.
Examples
HubSpot exports, Salesforce contacts, Apollo lists, outreach lists, customer records, partner databases.
Transformation Preview
Raw data in. Clean dataset out.
Drag across the preview to see messy records become standardized, deduplicated, enriched, and ready for upload.
Raw Input
| Name | Company | Phone | |
|---|---|---|---|
| john smith | JOHN@EMAIL | acme inc. | 555-1234 |
| Jane Doe | jane@email.com | null | (555) 5678 |
| JOHN SMITH | john.smith@email.com | Acme Inc | 555.9876 |
Clean Output
| Name | Company | Phone | Score | |
|---|---|---|---|---|
| John Smith | john@email.com | Acme Inc | +1-555-1234 | 87 |
| Jane Doe | jane@email.com | — | +1-555-5678 | 92 |
Data Processing Stack
Built with tools for parsing, cleaning, AI structuring, and reliable delivery
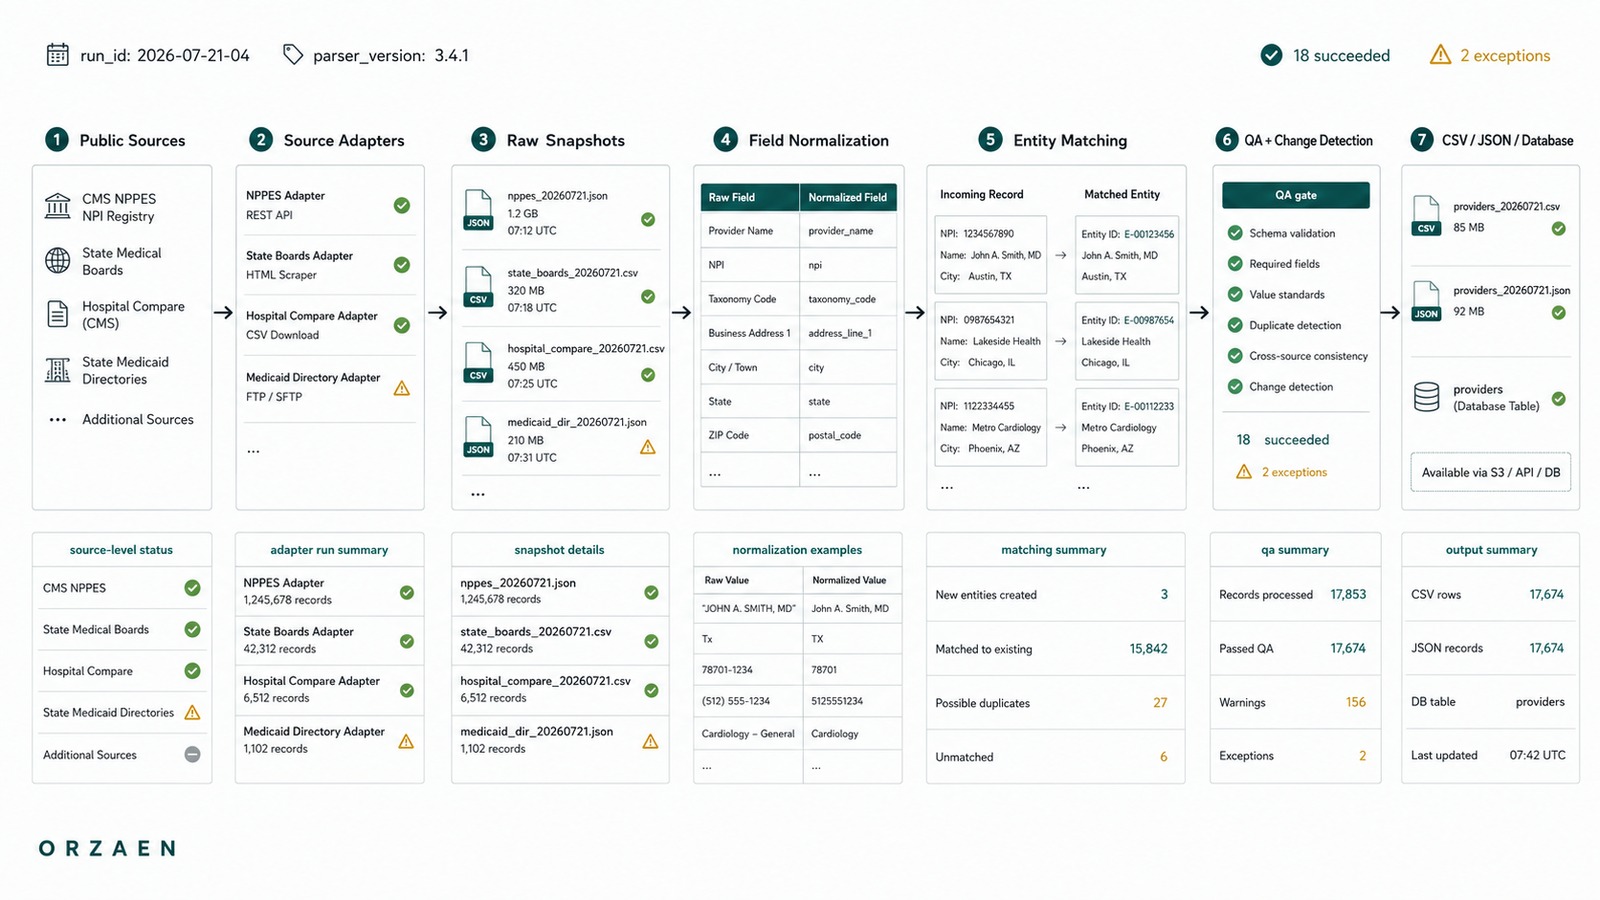
We combine file parsing, data cleaning, fuzzy matching, validation, enrichment APIs, and AI-assisted structuring depending on the condition of your source data and the output your workflow needs.
01
File Parsing & Intake
We process messy exports, spreadsheets, CRM files, supplier sheets, reports, and structured formats into clean working data.
 Python
02
Web & Scraped Data Cleanup
We clean noisy scraped datasets, HTML tables, broken URLs, duplicate listings, inconsistent text, and incomplete marketplace or directory records.
Python Pandas
03
Cleaning, Normalization & Matching
We fix columns, dates, phone numbers, casing, categories, missing values, labels, currencies, names, duplicates, and entity conflicts.
PandasPython04
AI-Assisted Structuring
We use AI where rules are not enough: messy text extraction, category mapping, record classification, entity matching, summarization, and field completion.
 Mistral AI
 Claude
 Gemini
 LangChain
 Hugging Face
05
Validation & Enrichment
We validate required fields, emails, formats, duplicate IDs, missing relationships, and enrich records through trusted lookup APIs.
 Great Expectations
 Pydantic
 Hunter.io
 Clearbit by HubSpot
 Google Maps API
06
Structured Delivery
Clean data is delivered as import-ready files, API payloads, reports, dashboards, database tables, or repeatable processing scripts.
 PostgreSQL
 Google Sheets
Data Quality Workflow
How we turn messy data into reliable output
We inspect the source, profile the quality issues, define cleanup rules, process and enrich the data, validate the result, and deliver clean files your team can actually use.
Review your data
We check the files, exports, lists, or datasets to understand what is messy and what clean output should look like.
Find quality issues
We identify duplicates, missing fields, bad formats, broken emails, weak labels, and rows that need review.
Clean and enrich
We fix formats, merge duplicates, fill missing fields, normalize values, and use AI when messy text needs structure.
Validate the result
We check required fields, bad values, duplicate IDs, rejected rows, and whether the data is ready to use.
Deliver clean output
You receive clean CSV, Excel, JSON, import sheets, reports, or dashboard-ready files with clear notes.
Controlled Workflow
Each step connects the source data, cleanup rules, validation checks, enrichment logic, review queue, and final delivery format into one controlled data processing workflow.
FAQ
Questions clients ask before sending messy data
Still have questions? We typically respond within 2 hours.
Automation Field Notes
Lessons from building automation that runs in production
Request a Quote
Turn messy data into reliable business output
Send your source files, exports, databases, scraped data, CRM lists, or product catalog issues. We’ll review the structure and suggest the best cleanup and enrichment path.
No perfect brief needed.
Project Brief